AI inference
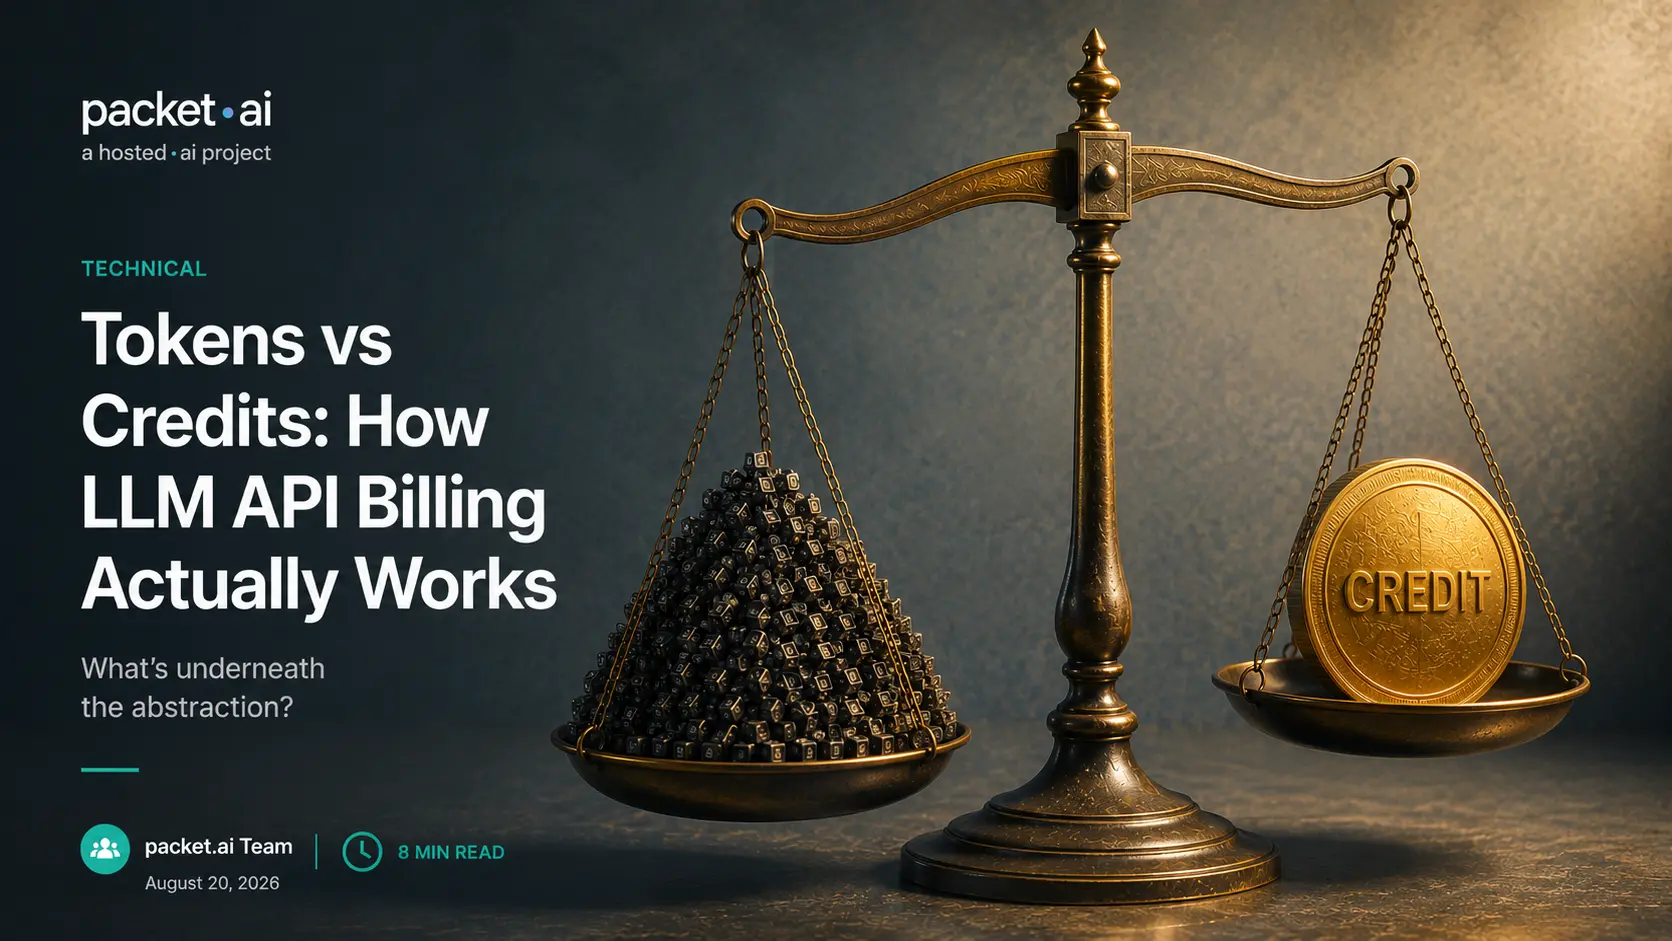
Tokens vs credits: how LLM API billing actually works
Every LLM API bills by the token underneath. Credits are the wrapper on top. Here is how the two relate, and how to tell a trustworthy credit system from one that isn't.
Every LLM API bills by the token underneath. Credits are the wrapper on top. Here is how the two relate, and how to tell a trustworthy credit system from one that isn't.
Most text-based LLM APIs measure underlying model usage in tokens, but the number you actually see is rarely a raw token count. Credits are often the billing layer placed on top: some providers charge you directly per token, others convert your usage into a prepaid balance you draw down against. The two aren't the same thing, and confusing them is how people end up with a $7,000 invoice they didn't see coming. The real question isn't whether credits are good or bad; it's whether the conversion rate between credits and tokens is actually published, and whether you can see which model consumed your balance. This guide explains what llm api credits actually are, how they relate to tokens, and where the abstraction helps versus where it hides real cost.
Key takeaways
A token is the basic unit of text that an LLM processes and generates as part of running inference, and it's the real unit every provider ultimately bills against. Token based pricing is the foundation everything else in this post sits on top of. In English, it's roughly three-quarters of a word in typical text, though tokenization varies by language and content type; a short word might be one token, a longer or less common one might split into two or three. Every API call has an input token count (your prompt) and an output token count (the model's response), and providers quote prices per million tokens, separately for each direction, since output tokens require more computation per token and typically cost two to five times more than input.
This is the layer that's genuinely fixed by physics and computation: processing and generating tokens costs real GPU time, and that cost doesn't change based on how a vendor chooses to present the bill to you. Whatever sits on top of token pricing, a subscription, a credit balance, a flat per-request fee, is a business decision layered over this underlying reality, not a different way of measuring the same thing.
AI credits are a provider-defined billing unit used to represent or abstract underlying model usage, usually tied to token consumption but not always exposed to the customer directly.
"AI credits" is a provider-defined billing unit that abstracts underlying usage, and what exactly it represents varies by product. Depending on the provider, a credit might be a prepaid balance denominated in dollars, an included monthly usage allowance, or a unit with a fixed monetary value assigned by the platform. The common thread: you're not billed in raw tokens directly, a credit layer sits in between, and each API call debits that layer at a rate the platform sets.
OpenRouter is a clean, well-documented example of this working as intended. It's a hosted aggregator sitting in front of dozens of underlying providers (OpenAI, Anthropic, Google, Meta, Mistral, DeepSeek, and others), and it bills through a single dollar-denominated credit balance rather than requiring a separate account and API key for every provider. Per OpenRouter's own documentation, inference pricing passes through from the underlying provider with no markup on the per-token rate, though a separate fee applies when credits are purchased. What you don't see as clearly: the dashboard shows credits debited per call, not the actual upstream invoice line, and if a model is served by multiple upstream hosts at different costs, which one your request routed to isn't surfaced. A small currency-conversion spread on top-ups and occasional double-billing on a failed-then-retried request are the real, if minor, costs of that convenience.
Two layers, moving independently
Any AI product with usage-based pricing has two separate layers. Layer one is the vendor's own billing abstraction: the subscription price, what a credit costs, how big the included pool is. This is the layer the vendor controls and can change on its own schedule, for its own business reasons. Layer two is the underlying provider's raw per-token API pricing, which moves for entirely different reasons, a model provider cutting prices, a new model replacing an old one, a peak-hour surcharge. Confusing the two is the single most common source of billing surprises: a vendor can hold a subscription's sticker price steady while quietly changing what a dollar of that subscription actually buys underneath, because the unit of account shifted.
Two recent, well-documented transitions from flat or request-based billing to credit-based billing show how differently this can go depending on execution.
Credits aren't inherently the problem here. Opacity is. A credit system is exactly as trustworthy as its published conversion rate. If you can see what a credit costs in real tokens, for a specific model, credits are just prepaid tokens with a currency layer, no worse than paying per token directly. If you can't, you're trusting the vendor's math without being able to check it, and that's the actual distinction this whole comparison comes down to.
Tokens and credits are the two most common units, but usage based pricing in AI products actually spans a wider range worth knowing about.
None of these is universally correct. Raw token billing is the most transparent but requires the customer to think in tokens. Credits add convenience and cross-model flexibility at the cost of an extra layer to audit. Flat pricing is the simplest to budget against but shifts risk onto the vendor. Task-based quotas are the newest response to a real problem: agentic workflows make per-token counting genuinely hard to reason about for anyone.
Whichever unit a provider bills in, a few questions separate a system you can reason about from one you can't.
packet.ai's Token Factory, currently in private preview, is being built around straightforward per-token billing: input and output metered separately, no credit-conversion layer, and scale-to-zero so idle traffic costs nothing rather than burning down a prepaid balance while unused. The goal is the auditability this post argues for, a rate you can check directly against what inference actually costs to run, not an abstraction you have to trust.
Join the waitlist for early access once it opens.
Last reviewed: August 20, 2026. For how raw per-token pricing breaks down across major providers, see the packet.ai LLM inference cost guide. For the fundamentals of what a token is and how inference works, see the What Is LLM Inference guide.
Same models. Same API. Fraction of the cost. Start free — no credit card required.
Start building →