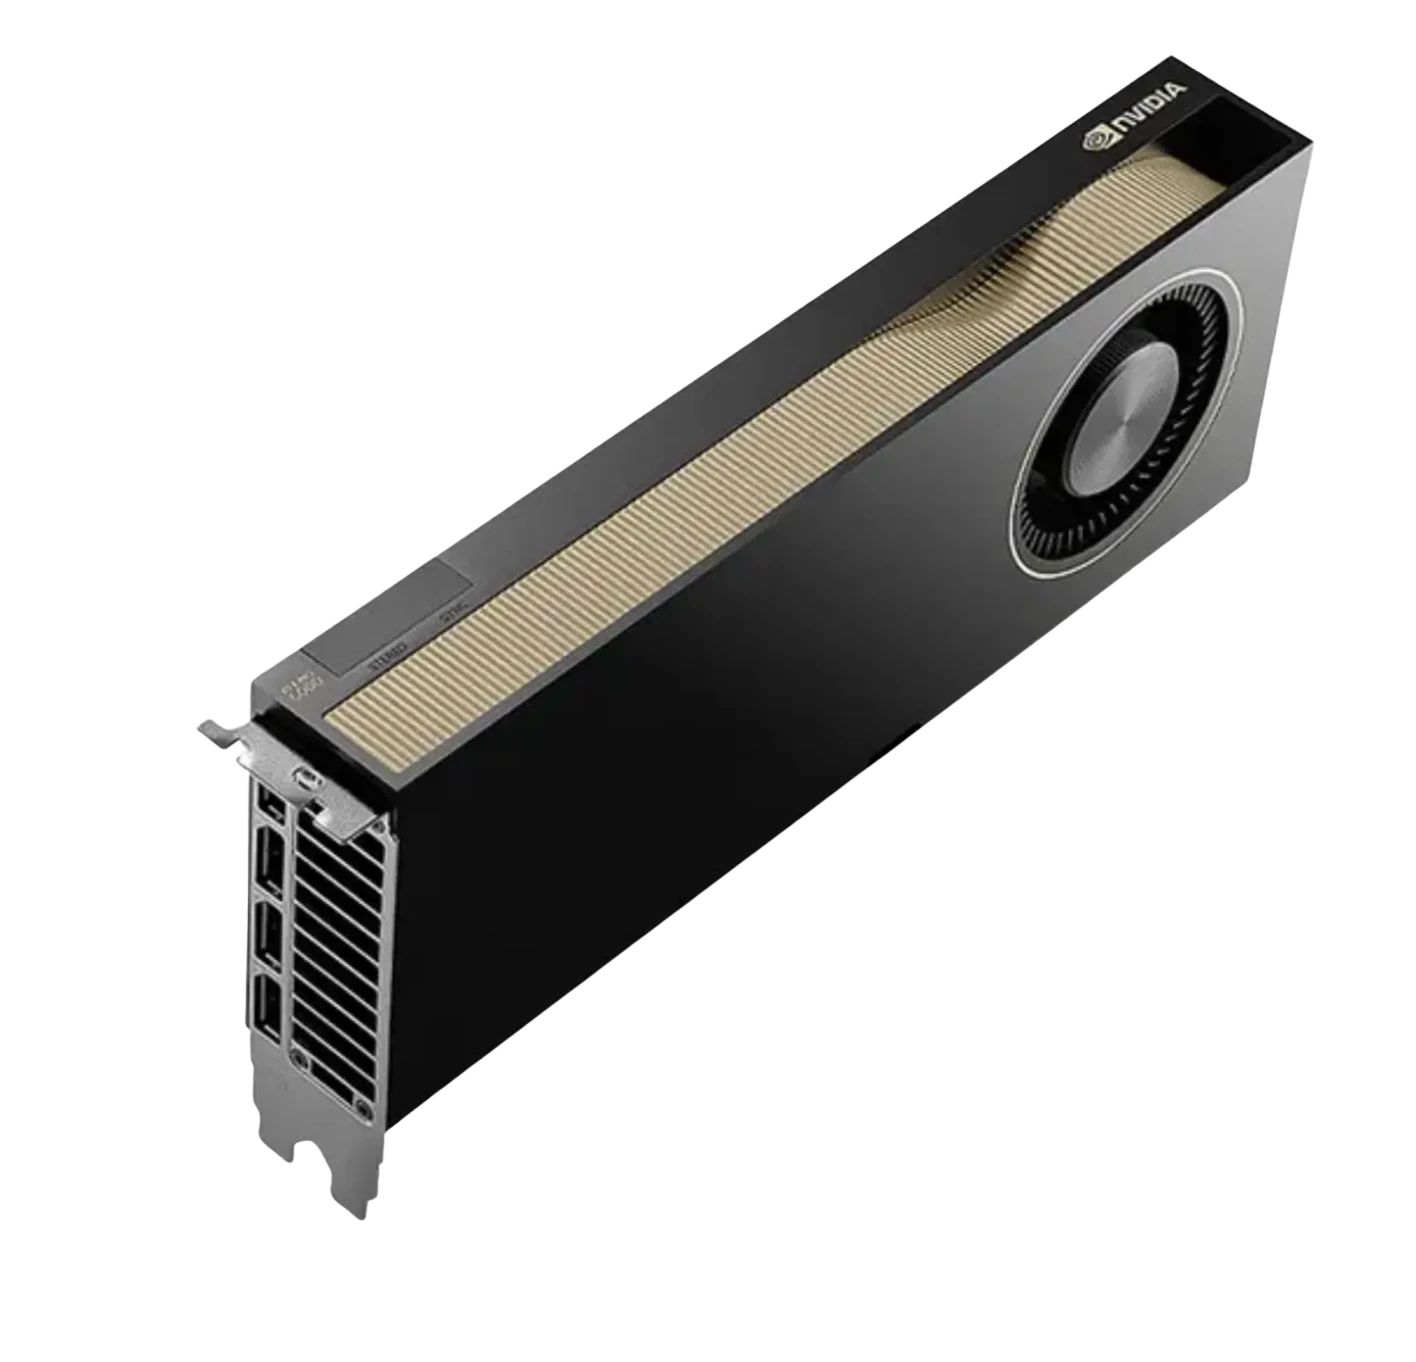
RTX PRO 6000 Blackwell
from $0.76/hr.
Blackwell with 96 GB of GDDR7 at $0.76 an hour. The most memory per dollar we sell, which makes it the default for fine-tuning and mid-size models.
Billed from your wallet · stop any time
What the RTX PRO 6000
is built for.
Tensor-core precisions: FP4, FP6, FP8, BF16, TF32.
Best at
- QLoRA and LoRA fine-tuning up to ~70B
- Serving 8B–32B models with long contexts
- Image and video generation
- Always-on dev workspaces
Launch from a terminal
Same card, same price as the console.
Will my model fit
on 96 GB?
Rules of thumb for weights plus a modest KV cache or optimizer state. Longer contexts and bigger batches need more.
| Workload | Needs | On a RTX PRO 6000 |
|---|---|---|
| Llama 3.1 8B · FP16 inference | ~18 GB | Fits |
| Qwen 32B · FP8 inference | ~36 GB | Fits |
| Llama 70B · 4-bit inference | ~42 GB | Fits |
| Llama 70B · FP8 inference | ~78 GB | Fits |
| Llama 8B · LoRA fine-tune (BF16) | ~24 GB | Fits |
| 32B · QLoRA fine-tune | ~40 GB | Fits |
| Flux.1 [dev] · BF16 | ~33 GB | Fits |
| SDXL · FP16 | ~12 GB | Fits |
Guides for
the RTX PRO 6000.
Benchmarks and sizing guides from our blog.
RTX PRO 5000 Blackwell in the Cloud: 48GB vs 72GB, Pricing, and Where It Fits
NVIDIA quietly shipped a 72GB version of this card with zero fanfare. Here is what actually changed, and what it means for renting one.
Rent RTX 6000 Pro in the Cloud – Deploy in Minutes on packet.aiPopular
The RTX 6000 Pro packs 96 GB of GDDR7 ECC into a workstation-class form factor and runs it at a price that makes H100 clusters look expensive for single-card inference.
RTX PRO 6000 Blackwell: 96GB GPU for LLM Inference from $0.76/hr
RTX Pro 6000 renters are paying up to 3.6x more than they need to. Here is the real price-per-GPU math, plus what 96GB actually unlocks for LLM inference.
Not the right fit?
Compare the fleet.
Every card on sale is billed hourly, with no contract.
Launch a RTX PRO 6000
from $0.76/hr.
Sign up, top up, launch. You'll be on a GPU in minutes.