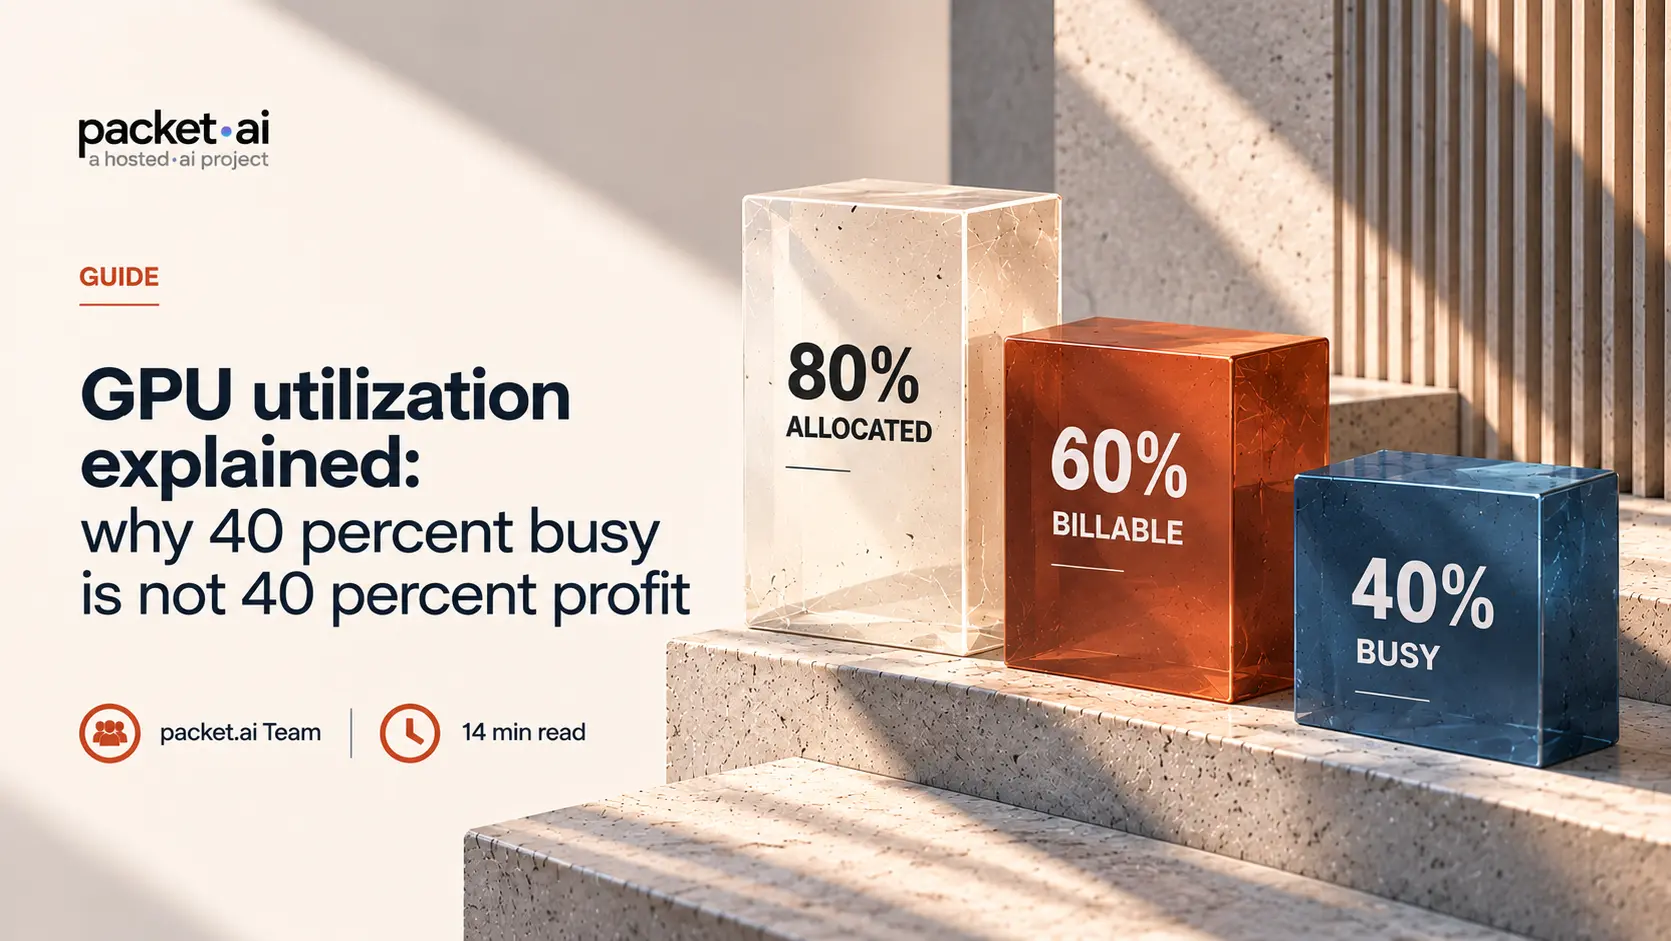
Your GPUs can be 80% allocated and still lose money. Here is the difference between allocated, busy and billable hours, with a worked example on one 8-GPU node.
Your GPUs can be 80% allocated and still lose money. GPU utilization sounds like one number, but a GPU cloud has at least three, and only one of them pays the bills. This guide separates allocated, busy and billable hours, walks one 8-GPU node through all three, and shows why a node that bills only 40% of its hours needs a rate two and a half times its base cost to cover its fixed cost. It is written for operators who run GPUs for other people, and it quotes no market rates: the example rates are arithmetic, not data.
Key takeaways
When someone says a fleet runs at 70% gpu utilization, ask which hours they mean. In a GPU cloud the same GPU can be counted three ways, and the numbers rarely match.
The busy number is the one most dashboards show, and it is narrower than it looks. NVIDIA's NVML defines GPU utilization as the share of the sample period in which at least one kernel was executing, which measures time, not how much of the chip was working. DCGM's SM activity is closer to real work, though NVIDIA's profiling documentation notes that an SM counts as active even while its warps wait on memory. It describes a value of 0.8 or more as necessary but not sufficient for effective use, and a value below 0.5 as likely indicating ineffective use. The packet.ai post on why the dashboard number misleads covers the measurement side, so this guide focuses on the business side.
GPU occupancy. It has two meanings. In CUDA, occupancy is the ratio of active warps to the maximum an SM can hold, a performance metric. In a rental business, gpu occupancy usually means the share of hours a GPU is rented. This guide uses it in the second sense, the share of GPU-hours assigned to paying customers. Depending on the billing model that may line up with billable utilization, but the two are not universally identical.
GPU efficiency. How much useful work a GPU does compared with what it could do, such as model FLOPs utilization in training. A GPU can be fully rented and still run inefficiently, because the customer, not you, decides what it does.
Compute utilization. The general term for how much available compute is in use. It is usually measured per resource, so a cluster can show high compute utilization on CPUs and low on GPUs at the same time.
The gap between booked and used is well documented in research clusters, though none of these are billed GPU clouds and all predate current hardware, so treat them as directional. Microsoft's Philly study (USENIX ATC 2019) observed that most GPUs in the cluster were allocated to users, which suggests high utilization, and warned that this metric alone is misleading: hardware utilization of the GPUs in use averaged only around 52%. Alibaba's PAI study (NSDI 2022, 6,742 GPUs, 2020 trace) found that on one class of 8-GPU machines, 74% of GPUs were allocated on average while average GPU utilization was 18%.
Revenue is billable hours times the rate you realize on them. On a dedicated rental the customer usually pays for allocated hours whether or not their GPU is busy, so busy hours matter to their experience and renewal, and billable hours matter to your income. GPU idle time on the customer's side is not your loss. Idle time on yours is. What counts as billable depends on your pricing model: a GPU can be reserved and billed regardless of workload, billed only while running, billed in fractions, or subject to minimum commitments. In this guide, billable hours are the GPU-hours that actually generate revenue.
The leak is between allocated and billable. Allocated hours that never bill include trials and credits, internal or evaluation workloads, hours lost to failed provisioning, and reservations sold at a discount deep enough that the realized rate is below break-even. None of these show up as idle on a scheduler, which is how a node can look 80% booked and still lose money.
Take the 5-year H100 server from the idle GPU cost model: a fixed monthly cost of $7,150, which is $1.22 per GPU-hour at 100% use across 5,840 GPU-hours (8 GPUs times 730 hours). That cost includes depreciation, committed colocation and an operations allowance, and excludes metered electricity, networking and financing. So the break-even rate used below is a fixed-cost break-even: the realized rate per billable GPU-hour that covers the modeled fixed monthly cost. It is not a full operating-profit calculation. The example is illustrative, so the hours are chosen to show the mechanics, not to describe a typical fleet.
One 8-GPU node, 5,840 GPU-hours in a month (illustrative)
Revenue follows the 60%. The customer's experience follows the 40%. Whether it pays depends on the rate.
Here the node is 80% allocated, but 20 points of those hours are unbilled trials, credits and internal use, so only 60% bill. Inside the billed hours, customers keep the GPU busy about 40% of the time overall. The same $7,150 divides three ways:
Billable hours are the right denominator for revenue, so the fixed-cost break-even rate is $2.04 per billable GPU-hour. Whether the node makes money depends on the rate it realizes on those hours, after discounts and credits. The table below uses example rates only to show the mechanics. They are not market rates, a quote or a forecast.
At 80% allocated, a $1.50 realized rate loses nearly $1,900 a month. The same node at $2.50 earns money. The utilization did not change, only the rate on the billable hours did, which is why allocated utilization on its own cannot tell you whether a fleet is healthy. The title is the same arithmetic in miniature: break-even rate rises as billable utilization falls.
Low gpu utilization in a GPU cloud tends to come from a handful of causes, and the production studies cited above document most of them.
Requests larger than use (workload). In Alibaba's cluster, the median instance requested about half a GPU and used about 0.042 of one, and users tended to ask for more than they needed. CPU and data bottlenecks (infrastructure). The same study found much of the low GPU use came from tasks spending their time on CPU work such as data fetching, which left GPUs idle for most of the time and not because compute demand was low. Fragmentation and locality (scheduling). Microsoft found that 16-GPU jobs averaged lower utilization when spread across more servers, as low as about 28% across eight servers. Reserved capacity that sits unused (scheduling). Alibaba's high-end V100 machines, reserved for a small number of important tasks, averaged only 49% of GPUs allocated. Uneven demand (demand). Task submissions follow daily and weekly patterns, so a fleet sized for the peak idles through the valleys. Unbilled allocation (commercial). Trials, credits and internal use hold capacity without paying, as the worked example above shows.
Pricing. Work from the realized rate, not the list rate. Set a floor from your break-even at the billable utilization you expect, and watch how much of your billed volume sits at discounts below it. Committed and on-demand tiers fill hours differently, so check each against your break-even separately.
Scheduling. Packing and reservation policy move utilization. Alibaba reported that a reserve-and-pack policy, which keeps high-end GPUs for demanding tasks and packs the rest onto other machines, cut average queueing delay by 68% for high-GPU tasks and 45% overall. That is a result from one cluster, but it shows scheduling policy matters as much as hardware.
Demand channels. Hours that stay idle after scheduling are the ones a second source of demand can fill, such as a marketplace or reseller channel alongside direct sales. The packet.ai guide to the five ways to turn idle GPUs into revenue sets out the routes and their constraints, and what an idle GPU costs puts the fixed-cost side in numbers.
Sharing a GPU between tenants changes what you sell. Instead of whole GPUs you sell fractions, which can put more billable hours on the same hardware but turns the ladder above into fractional GPU-hours, and raises the questions of contention and isolation. With fractional sharing, the denominator stops being whole-GPU hours and becomes the share of GPU capacity actually sold.
Alibaba's data gives one measured case. With GPU sharing, its cluster needed about half the GPUs it would have without it, and up to 73% fewer at the busiest hour. Heavy utilization at 95% or more was measured in only 7% of cases, and few of those GPUs ran several instances, so contention stayed limited. The mechanisms differ in what they guarantee: NVIDIA Multi-Instance GPU partitions a GPU with isolated memory and bandwidth, Multi-Process Service shares a GPU without isolating failures, and software time-slicing adds context-switching overhead, as characterized in that 2022 paper. Newer hardware and software may differ, so check current documentation before you design around them.
The practical effect is on measurement. If you sell fractions, count billable utilization in fractional GPU-hours, and track realized revenue per physical GPU-hour. Treat any vendor claim about revenue multiples from multi-tenancy as a claim until you have measured it on your own workload.
There is no universal good number, because published measurements follow the workload. A study of the Acme LLM training clusters (USENIX NSDI 2024) reported median GPU utilization of 97% and 99% on its two clusters, far above the mixed-workload clusters in earlier traces. Average gpu utilization across a fleet hides this kind of difference, so split it by workload type before you compare it with anything.
The target that matters is yours: billable utilization comfortably above the fixed-cost break-even point for your modeled costs and realized rates. The formula is one line.
Fixed-cost break-even billable utilization
= cost per GPU-hour at 100% use / realized rate per billable GPU-hour
Measure all four series separately every month: allocated hours from the scheduler, billable hours and realized rate from billing, busy time from NVML, and SM activity from DCGM. The gaps between them are the work. A large allocated-to-billable gap is a commercial problem. A large billable-to-busy gap is a customer-experience and retention risk. A low SM activity is the customer's efficiency problem, but it shows up in renewals.
See how operators fill idle hours on the packet.ai provider page, or apply to list capacity if you want a second demand channel. For the earnings side of the same math, see the H100 and B200 utilization math.
Retrieved October 8, 2026. The cluster studies cover research and internal ML platforms on older GPUs, not billed GPU clouds, so they illustrate the gap between allocation and use and are not benchmarks for your fleet.
Last reviewed: October 8, 2026. The worked example uses example hours and example rates to show arithmetic. It contains no market rates, no earnings figures and no guarantee of income. The break-even shown is a fixed-cost break-even, not a full operating-profit calculation, and it excludes metered electricity, networking and financing. For packet.ai's current provider requirements and terms, see the provider page.
Same models. Same API. Fraction of the cost. Start free — no credit card required.
Start Building →