Token Factory is live: free LLM API for DeepSeek and MiniMax
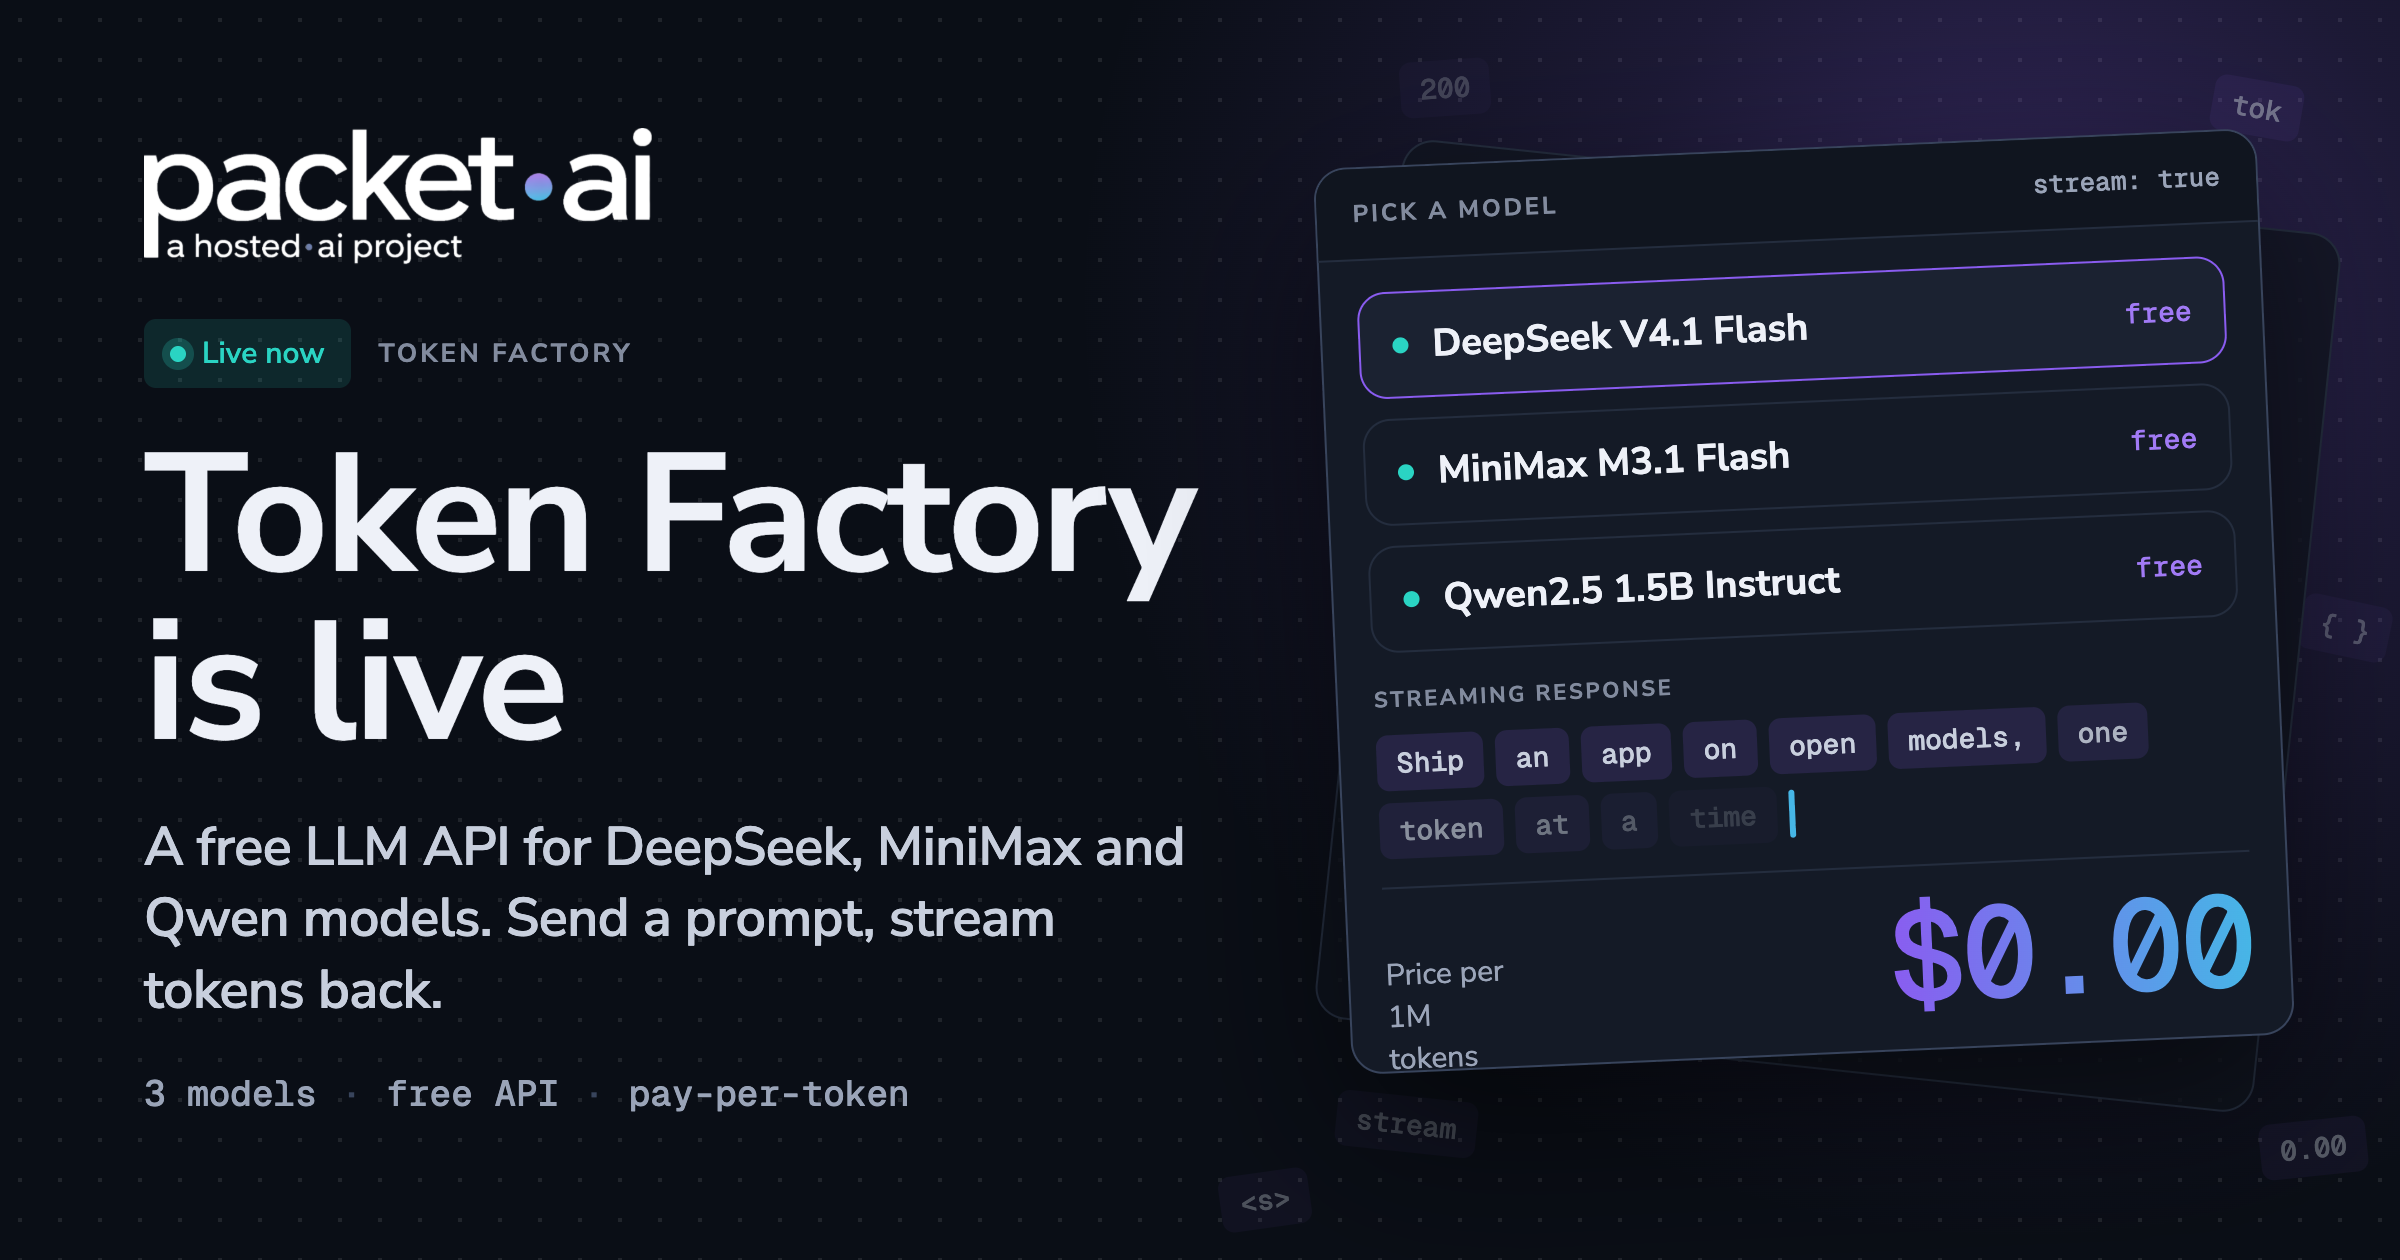
DeepSeek V4.1 Flash, MiniMax M3.1 Flash and Qwen2.5 1.5B Instruct just went live on Token Factory, free for every packet.ai user. Here is what each model does and what it costs everywhere else.
packet.ai Team
November 17, 2026
Token Factory, packet.ai's pay-per-token LLM inference API, is now live and free for every user - with DeepSeek V4.1 Flash, MiniMax M3.1 Flash and Qwen2.5 1.5B Instruct all available at no cost.
Key takeaways
Token Factory, packet.ai's pay-per-token LLM inference API, launched free for all users with no waitlist step left to clear.
Three models are live at launch: DeepSeek V4.1 Flash (NVFP4), MiniMax M3.1 Flash and Qwen2.5 1.5B Instruct.
DeepSeek V4.1 Flash ships a 1M-token context window and runs in NVIDIA's 4-bit NVFP4 format, under an MIT license.
MiniMax M3.1 Flash also offers a 1M-token context window and is priced at $0.15 per million input tokens and $0.60 per million output tokens on most third-party hosts - free on Token Factory.
Qwen2.5 1.5B Instruct is a 1.5B-parameter Apache 2.0 model built for lightweight, low-latency tasks.
packet.ai has said Token Factory launches free to drive adoption first, with monetization decisions to follow later.
Most inference APIs make you pick a model, check a pricing page, and estimate a monthly bill before you send a single request. Token Factory removes that step for now. Every model on the platform, including two that shipped within the last 60 days, is available under the same account with no separate sign-up and no cost.
That matters most for the builders who feel GPU and API costs before they feel anything else: solo developers testing a prototype, startups running early user tests, and students comparing models for a class project. A free tier with real, current models removes the question of whether to spend money before you know if an idea works.
What is packet.ai's Token Factory
Token Factory is packet.ai's hosted inference API for large language models. Instead of renting a GPU and managing your own serving stack, you send a request to Token Factory's endpoint with a model name and a prompt, and it returns a completion - the same request pattern used by most hosted LLM APIs.
packet.ai built Token Factory alongside its GPU cloud, where customers already rent on-demand NVIDIA GPUs for training and fine-tuning. Token Factory covers the other half of that workflow: running inference on a model without provisioning any hardware yourself.
Token Factory is free for every user at launch. packet.ai has said this is a deliberate choice to drive adoption before it makes any monetization decisions, so there is no published end date for the free period right now.
Models available on Token Factory right now
Three models are live on Token Factory at launch, spanning a large reasoning model, a fast agentic model and a small instruct model.
DeepSeek V4.1 Flash combines a 552B-parameter backbone with a 196B-parameter "Engram" conditional-memory component, for roughly 763B parameters total, and supports a 1M-token context window. The build on Token Factory uses NVIDIA's NVFP4 format, a 4-bit floating-point format that cuts the model's memory footprint well below a standard FP16 or FP8 build while keeping output quality close to the original. It ships under an MIT license.
MiniMax M3.1 Flash is MiniMax's fast model for agentic and coding workloads, also built with a 1M-token context window. MiniMax ran its own free preview for the model that ended October 22, 2026; after that, most third-party hosts price it at roughly $0.15 per million input tokens and $0.60 per million output tokens. On Token Factory, it runs free with no preview cutoff announced.
Qwen2.5 1.5B Instruct is Alibaba's instruction-tuned 1.5B-parameter model, with a 32,768-token context window and generation capped at 8,192 tokens per response. It is small enough to respond quickly and cheaply at scale, which is why teams use it for classification, short completions and other tasks where a 100B+ parameter model is overkill.
Model
Context window
Parameters
License
On Token Factory
DeepSeek V4.1 Flash (NVFP4)
1M tokens
763B total
MIT
Free
MiniMax M3.1 Flash
1M tokens
Not published
Proprietary
Free
Qwen2.5 1.5B Instruct
32,768 tokens
1.5B
Apache 2.0
Free
What DeepSeek V4.1 Flash API and MiniMax API cost elsewhere
DeepSeek V4.1 Flash and MiniMax M3.1 Flash are both available through several hosted inference providers, and none of them are free once a launch promotion ends.
DeepSeek V4.1 Flash costs $0.22 per million input tokens and $0.66 per million output tokens on Fireworks AI, one of its hosting partners. MiniMax M3.1 Flash lists at $0.15 per million input tokens and $0.60 per million output tokens on most providers, including Together AI and Fireworks, after MiniMax's own free preview period ended on October 22, 2026.
On Token Factory, both models currently cost $0 per token. For a team running enough volume that token costs show up on a budget line, that is the entire pitch: the same open-weight or hosted models, the same request pattern, without a bill while the free period lasts.
Why a free LLM API changes the math for builders
✓ Good fit for Token Factory today
Prototyping and testing a product idea before committing budget
Comparing DeepSeek V4.1 Flash, MiniMax M3.1 Flash and Qwen2.5 1.5B Instruct on the same task
Student and hobby projects that need real models, not a toy demo
Low-latency classification or short completions with Qwen2.5 1.5B Instruct
⚠ Plan for change
packet.ai has said it will make monetization decisions after the free launch period
No public rate limit has been published for the free tier yet - check your dashboard for current limits
Production workloads with contractual uptime needs should still plan for a paid tier eventually
Most pay-per-token APIs ask a builder to commit to a cost estimate before they know whether a model fits their use case. A free tier removes that step entirely. You can run the same prompt against DeepSeek V4.1 Flash's 1M-token context and Qwen2.5 1.5B Instruct's faster, smaller footprint, and pick based on output quality and latency instead of your remaining budget.
How to start using the free AI API on Token Factory
1
Create a packet.ai account
Sign up for packet.ai if you don't already have an account. No card is required to use Token Factory.
2
Open the Serverless models page
Go to dash.packet.ai/serverless and choose DeepSeek V4.1 Flash, MiniMax M3.1 Flash or Qwen2.5 1.5B Instruct from the model list.
3
Send your first request
Generate an API key from the dashboard and call Token Factory's endpoint with the model name you picked. Every response is free for now, with no separate top-up needed.
Frequently asked questions
Token Factory is packet.ai's pay-per-token LLM inference API. You send a prompt to a hosted model through an API call instead of renting GPUs and running your own serving stack. It launched alongside packet.ai's GPU cloud and is currently free for all users.
Yes. packet.ai made Token Factory free for every user at launch, with no card required to sign up. packet.ai has said this is meant to drive adoption, with monetization decisions to be made later - there's no published end date for the free period yet.
Three models are live at launch: DeepSeek V4.1 Flash (NVFP4), a 763B-parameter model with a 1M-token context window; MiniMax M3.1 Flash, also with a 1M-token context window, built for fast agentic tasks; and Qwen2.5 1.5B Instruct, a small 1.5B-parameter model for lightweight, low-latency jobs.
DeepSeek V4.1 Flash, released September 10, 2026, pairs a 552B-parameter backbone with a 196B-parameter "Engram" conditional-memory component for roughly 763B parameters total, and supports a 1M-token context window. The NVFP4 build on Token Factory uses NVIDIA's 4-bit format to shrink the model's memory footprint, and it ships under an MIT license.
MiniMax built M3.1 Flash, released October 19, 2026, for fast agentic and coding workloads with a 1M-token context window. Outside Token Factory, it's priced at $0.15 per million input tokens and $0.60 per million output tokens on most hosts after MiniMax's own free preview ended on October 22, 2026.
packet.ai has said Token Factory launches free to drive fast adoption, with monetization decisions to follow once usage grows. No end date for the free period has been announced, so it's worth checking packet.ai's own channels before planning long-term production spend around it.
Last reviewed: November 17, 2026. Ready to try it? Open Token Factory's model picker and run a request against any of the three models above.